Benchmark
Protocol, corpus and results
Every error rate and speed on this site comes from the evaluation described here. Definitions first, then the protocol, then the numbers.
Definitions
WER: word error rate
WER = (S + D + I) / N
- S
- Substitutions: a reference word replaced by a different word.
- D
- Deletions: a reference word missing from the output.
- I
- Insertions: an output word with no counterpart in the reference.
- N
- Number of words in the human reference.
A WER of 11.4% means 114 errors per 1,000 reference words. WER can exceed 100% when the output inserts many words.
DER: diarization error rate
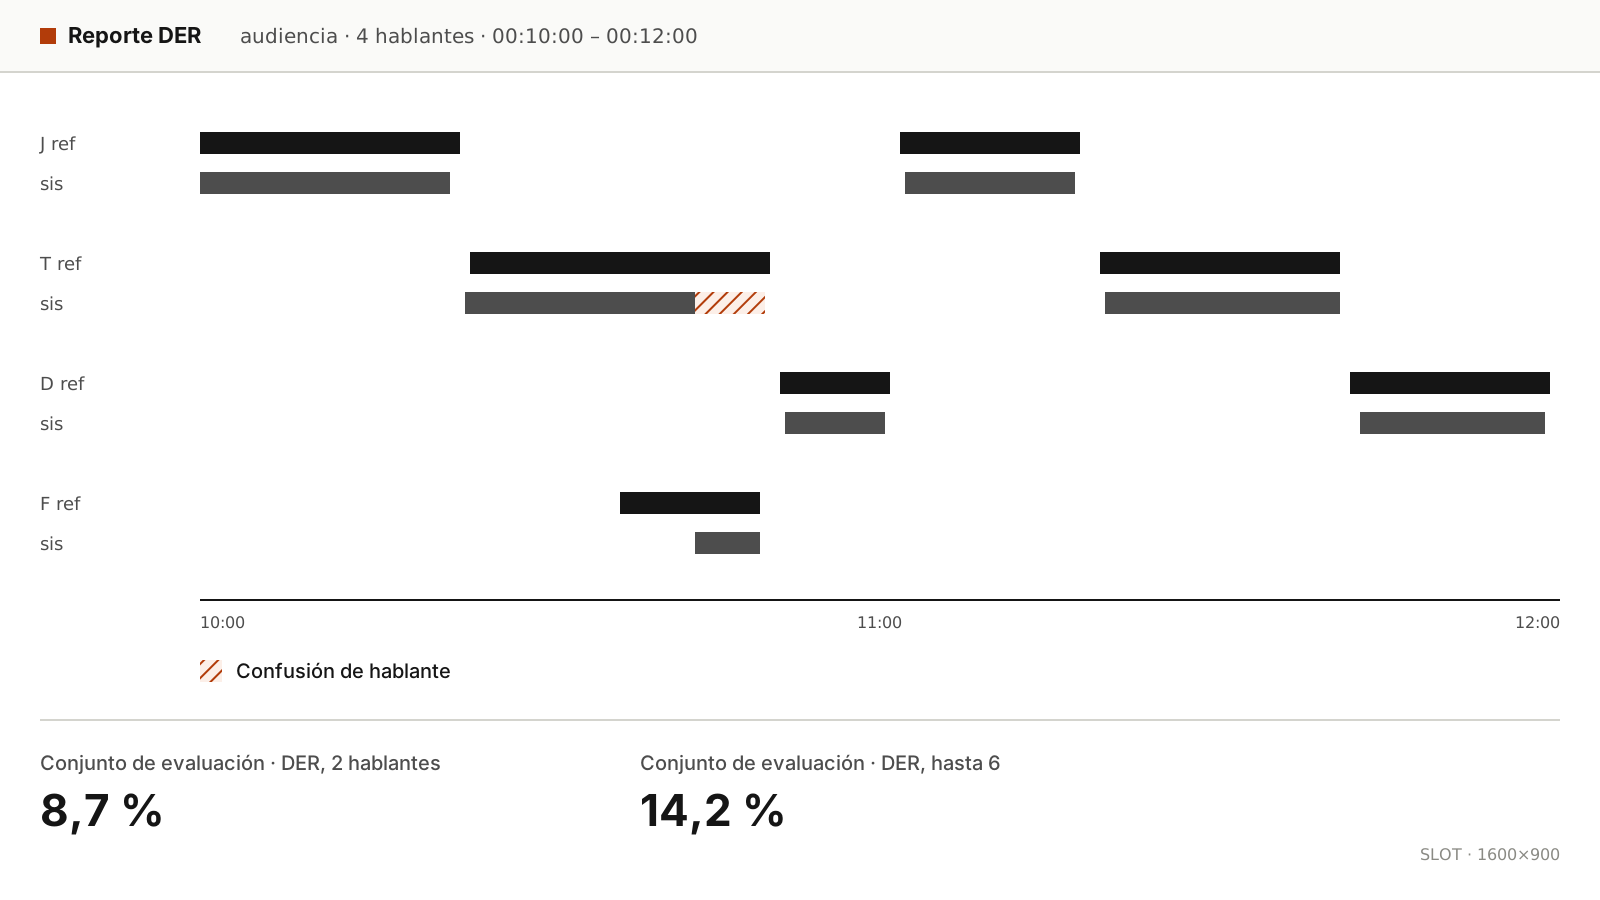
DER = (missed + false alarm + confusion) / total speech time
- Missed
- Speech labelled as silence.
- False alarm
- Silence or noise labelled as speech.
- Confusion
- Speech attributed to the wrong speaker.
DER measures who spoke when, not what was said. It is scored in seconds and is independent of WER.
Protocol
- The evaluation set is split from training by speaker: no speaker in it appears in the training data.
- Both systems receive the same files at their original sample rate. No denoising, no manual segmentation.
- Whisper large-v3 runs locally from its open weights, with the language fixed to Spanish and default decoding settings.
- Prosodia Local runs on one NVIDIA L4 with no client glossary loaded.
- References are transcribed by hand and checked by a second annotator.
- Reference and output are normalized the same way before scoring: lower case, punctuation removed, numbers written as words. Written accents are kept, so “esta” and “está” count as different words.
- WER is computed over all the words of each recording type pooled together, not averaged per file.
Corpus
Corpus: 1,900 hours
| Source | Hours | Status |
|---|---|---|
| Recorded by Prosodia in Rosario | 214 h | Own |
| Licensed from third parties | 1,686 h | Licensed |
| Total | 1,900 h |
Evaluation: 15 hours
| Source | Hours | Status |
|---|---|---|
| Common Voice, Argentine Spanish (es-AR) | 6 h | Public, CC0 |
| Recorded by Prosodia | 9 h | Own, never used for training |
| Total | 15 h |
The evaluation set is separated by speaker. None of its speakers appears in the training data.
Results by recording type
| Recording type | Prosodia Local | Whisper large-v3 | Difference |
|---|---|---|---|
| Telephone, 8 kHz (contact center) | 11.4% | 28.3% | −16.9 pts |
| Courtroom, 16 kHz (hearings) | 6.2% | Not measured yet | — |
| Clean read speech | 4.1% | 5.1% | −1.0 pt |
Whisper large-v3 is a general multilingual model and was not adapted to this audio. On clean read speech the two systems are close. The gap opens on 8 kHz telephone audio, where voseo, elision and a narrow frequency band combine.
Whisper large-v3 has not been run on the courtroom set yet. We publish the figure when it is measured; we do not extrapolate it.
Breakdown by accent
| Accent group | Provinces | Prosodia Local WER |
|---|---|---|
| Rioplatense, Litoral | Santa Fe, Entre Ríos | Pending |
| Rioplatense, Buenos Aires | Buenos Aires city and metro area | Pending |
| Cordobés | Córdoba | Pending |
| Cuyano | Mendoza, San Juan, San Luis | Pending |
| Noroeste (NOA) | Salta, Jujuy, Tucumán, Catamarca, Santiago del Estero | Pending. Known limit |
The NOA accent is a documented failure. The reason is on What it does not do.
Diarization
| Speakers in the recording | DER |
|---|---|
| 2 | 8.7% |
| Up to 6 | 14.2% |
Diarization supports up to 6 speakers per recording. Overlapping speech longer than 1.5 s is a known failure; see What it does not do.
Speed
0.42× real time on one NVIDIA L4. A one-hour recording is ready in about 25 minutes. Processing is batch only; there is no live streaming.
What is licensed and what is ours
- 214 h were recorded by Prosodia in Rosario, with written consent from every speaker. Prosodia owns them.
- 1,686 h are licensed from third parties for model training. Prosodia does not own them and does not redistribute them.
- The 6 h of Common Voice are public under CC0 and are used only for evaluation.
- The 9 h of Prosodia evaluation audio are never used for training.
- Customer audio is not used for training. It stays on the customer’s server.
These are our own measurements. The bench test runs the same scoring on your audio.